
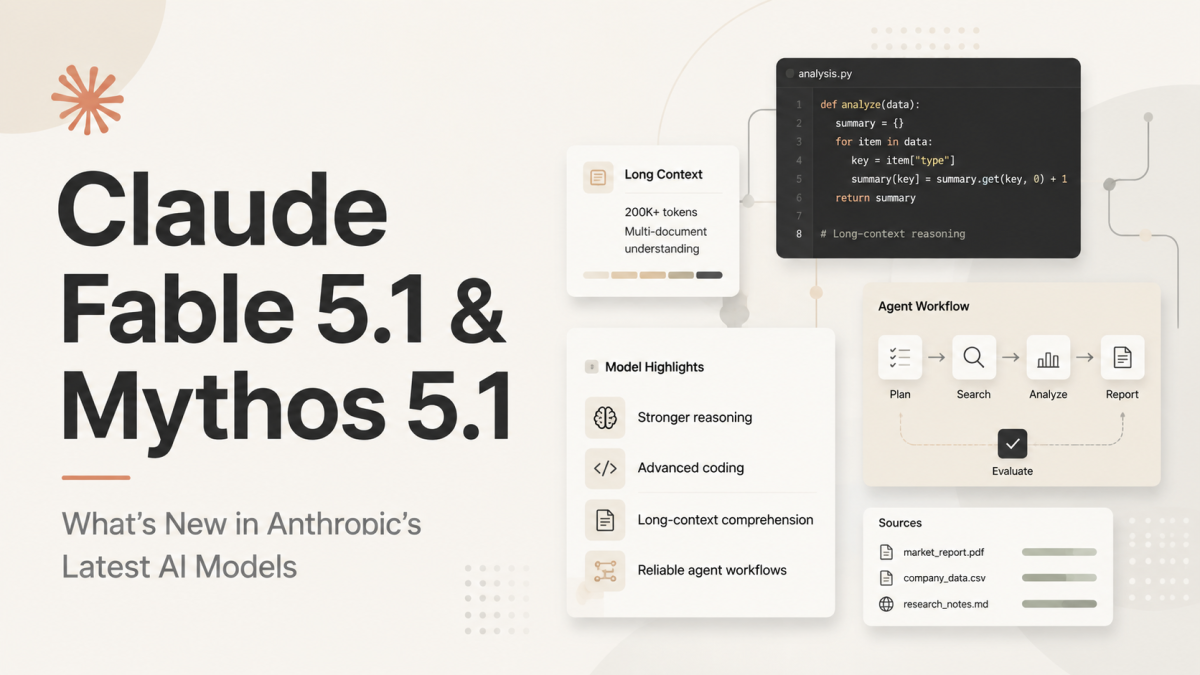
Anthropic has just released Claude Fable 5.1 and Claude Mythos 5.1, its latest AI models designed for advanced coding, long-running AI agents, research, and complex professional tasks.
The release was announced on September 1, 2026, and this update is more notable than a typical minor “.1” version. Fable 5.1 brings significant improvements in coding and agent tasks, while Mythos 5.1 is a specialized version for approved cybersecurity and life sciences organizations.
Fable 5.1 and Mythos 5.1
Fable 5.1 and Mythos 5.1 are both built on the same underlying model.
The main difference between them is the safeguards in place.
Fable 5.1 is the generally available version and has stricter limits on sensitive topics in cybersecurity, biology, and chemistry.
Mythos 5.1 provides broader access to these features, but Anthropic only offers it to approved organizations and researchers.
Mythos is not a smarter model; it uses the same base model but has a different safety and access setup.
Better Coding and AI Agents
One of the biggest improvements in Fable 5.1 is its coding ability.
Anthropic achieved a score of 73.4% on the CursorBench 3.2.0 test, while Fable 5 scored 70.5%.
On the Terminal-Bench-Science 0.1 test, the improvement is even bigger. Anthropic reports that Fable 5.1 scored 52.6%, compared to 24.7% for Fable 5.
These results come from Anthropic’s own benchmarks, so they are not independent. Still, they show a clear improvement rather than just a minor update.
Fable 5.1 also performs well on long-running agent tasks. Instead of just answering a single prompt, it can plan multiple steps, use different tools, check files, recover from errors, and keep working toward its goal over time.
Anthropic shared tests where the model completed coding and machine learning tasks on its own for several hours.
The most interesting part of this release is this:
AI models are gradually shifting from just answering questions to handling multi-step tasks.
1 Million Token Context Window
Claude FablClaude Fable 5.1 has a context window of 1 million tokens and can generate up to 128,000 output tokens. is very useful for large codebases, research projects, long documents, and agent workflows where the model has to keep track of a large amount of information.
For developers, the API model ID is:
claude-fable-5-1
Anthropic lists the standard API price at $10 per million input tokens and $50 per million output tokens.
Prompt-cache reads cost just $0.25 per million tokens, which can help lower costs for long-running agents that reuse the same context.
Security Safeguards Are Less Aggressive
Anthropic has also updated Claude’s cybersecurity protections. Fable 5.1 results in about 60 percent fewer safeguard interventions during Claude Code sessions than Fable 5.
This matters because security filters can sometimes block legitimate defensive actions if vulnerability-related commands or terms look suspicious.
Fable 5.1 can likewise be used to identify vulnerabilities in source code, although more sensitive capabilities for exploits remain restricted.
Should You Use Fable 5.1?
Fable 5.1 is more than you need for everyday questions.
Anthropic recommends using Claude Opus 5 for most regular tasks, and switching to Fable when you need more reasoning, a bigger context window, or long-running autonomous tasks.
This update looks like a big step forward for developers, researchers, and companies working with AI agents.
What’s more important is not just another bump in benchmark numbers.
AI models are noAI models can now work for long periods, use tools, recover from errors, and handle more complex tasks without constant supervision. At which Fable 5.1 could become truly useful.